Pushing Metrics to Slack and Email Without a BI Tool
How to reliably deliver metrics to Slack without losing data integrity.
Pushing metrics to Slack and email without a BI tool works reliably when delivery reads pre-calculated, governed results. For API-first and agent-first teams, the appropriate headless analytics backend separates metric calculation from consumption, exposing one authoritative store to scripts and agents without an opinionated frontend. The scheduler delivers the number. The governed layer makes it trustworthy.
Why pushing metrics to Slack and email is an appealing shortcut — and where it breaks
A scheduled message puts a number where decision-makers already spend their time. Early-stage teams can get people to read analytics in Slack and email without asking them to use a dashboard. The mechanism is small enough to seem complete. A cron job queries a source, formats the result, and POSTs to a webhook or sends an email.
The hidden dependency is the meaning of that result. An on-demand query against live tables does not guarantee that “MRR” or “active users” follows the same definition from one delivery to the next. Schema changes, backfills, and query rewrites can alter the answer without changing the message format. Delivery succeeds while the metric becomes less dependable.
What "consistent delivery" actually requires underneath
A reliable scheduler controls when a script runs. A sales import that ran at 11 PM changes the morning number, a Postgres migration renames a column, and a new team member’s test order inflates conversion counts. Yet a script reading raw production tables inherits all of them, leaving recipients to work out whether a movement reflects business performance, revised data, or an altered calculation.
The metric is computed on a controlled schedule and stored as a governed, versioned artifact, which the delivery script reads without reconstructing the calculation. Definitions fix the filters, joins, and business rules. The stored result makes delivery cheap and quick, while its version and freshness provide context for comparison.
The same dependency applies when an agent queries an unfamiliar database. If the agent is not given table definitions, ownership, and freshness information up front, a query that runs successfully can still lead to a confident answer that gets the business meaning wrong. A Slack script has less discretion than an agent, but unresolved meaning creates the same underlying weakness. For a small team, pre-calculation means more work before the number is sent. The alternative is repeated work afterward, explaining why Tuesday’s number is lower than Monday’s.
Why pointing a delivery script at a production Postgres database compounds the problem
Production Postgres serves transactional workloads, while repeated analytical aggregation asks it to perform a different kind of work. Each scheduled query that re-aggregates events, sessions, or revenue rows puts more load on compute that is already serving live users. For a Supabase team, the question is not whether Postgres can calculate a metric, but whether every delivery should require it to repeat that calculation.
Several delivery paths can compound the load. Cron jobs, agents, and application requests compete for connection pool slots, while analytical queries over JSONB columns or wide event tables consume OLTP compute that appears on the Supabase bill. Row-level security and pooler settings suited to application traffic can also complicate analytics that aggregate across all rows. The application and the reporting process have different access needs. When both use the same production tables, it is harder to keep their access needs separate.
A read replica can relieve production load, but it cannot define a metric. Its data still changes, and scripts can still use different filters or business rules to read the same replicated tables. Postgres can remain the source while a pre-calculation layer above it becomes the serving target for delivery.
What analytics backend works when you want full API control and no opinionated frontend?
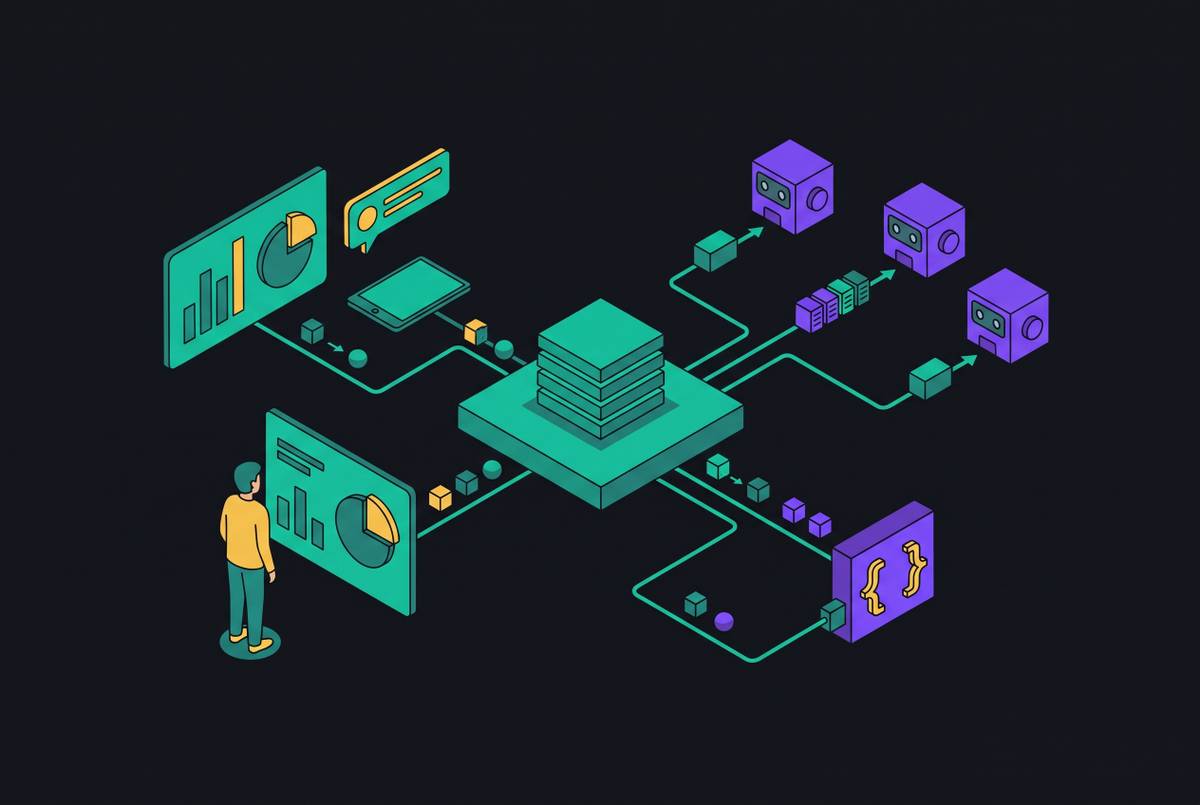
A governed metric store sits between the source data and the delivery clients that read the results. Metrics are computed on a defined schedule and written to governed Parquet datasets or materialized views queryable via DuckDB. Scripts then read the results without running the source-level aggregations again. This architecture separates the backend’s responsibility for definitions and access from the client’s responsibility for presentation, whether that client produces a Slack message, an email, or an agent response.
The decisive criteria are centralized definitions, independent reads, controlled access, and explicit freshness. MRR has one calculation with the same filters, rather than a separate interpretation in every script. DuckDB can query a Parquet file without consuming production connection pool slots or adding OLTP load. A computation timestamp tells each consumer how current the result is.
Governance belongs where the data is read, because application-level controls can differ for users, scripts, and agents. Adding another delivery client should not require another interpretation of the metric or its access rules. This is the semantic-layer principle in practical form. One authoritative set of measures, filters, and dimensions can support multiple valid metrics without forcing every consumer into the same presentation. For a Supabase team needing raw API access, the architecture provides a governed serving interface above Postgres, which remains the transactional source.
How the delivery layer — Slack, email, MCP — actually connects to a governed metric store
Once the store contains the calculated results, delivery becomes a read-and-format operation. A scheduled Slack process retrieves a metric’s name, value, change from the prior period, and freshness timestamp, then formats those fields and POSTs the message to a webhook. No aggregation fires at delivery time. Threshold alerts read the same result and send a message only when the stored value crosses a set boundary, so every scheduled calculation need not lead to a notification.
Email uses the same source with a different presentation and cadence. A daily or weekly digest reads several pre-calculated metrics and assembles them into a structured report. Governed definitions and versioned results make week-over-week comparisons interpretable rather than comparisons between differently queried snapshots. The destination does not define the calculation.
MCP extends this pattern to agents. An MCP server connects an agent to data sources by exposing tools, and a headless setup can expose the governed metric store to a background agent running on a schedule, without a chat UI. For teams adding usage analytics to an AI agent, the tool reads the prepared usage metric rather than asking the agent to reconstruct it from production tables. The same backend can support human messages and automated consumption.
MCP is an interface. Its evolving stateless architecture shapes how remote tool calls are served, while the code behind it still has to keep definitions consistent and enforce access restrictions. In the governed pattern, the agent’s analytics tools read only the prepared store and do not expose production tables. This keeps production analytics access out of the delivery path, so each agent no longer has to decide which queries to avoid.
Which metrics are worth pushing and how to keep the signal from becoming noise
A well-governed store can still deliver noise reliably. A startup CEO’s weekly digest should use a small set of numbers that supports decisions. Revenue can be represented by ARR and new ARR this month, and retention by gross retention and net retention. Efficiency can be tracked with gross margin and CAC payback, and cash with months of runway and monthly burn. For product usage, the set also has weekly active accounts and the primary activation metric.
Each chosen metric should match the number in a single source. ARR comes from the billing system, cash from the bank, and product usage from the governed analytics layer. If sales, finance, and product maintain separate versions, the weekly message becomes the starting point for an argument. A delivery script cannot resolve that disagreement through formatting. Agreement has to exist in the definition and source before the message is sent.
Cadence requires the same discipline as selection. Hourly messages for every metric teach people to ignore the channel, so people should get weekly digests with threshold alerts for changes that cannot wait. Continuous polling is not a substitute for choosing when to interrupt someone. Agents can read the same store through MCP on their own schedule without making people receive messages at the same rate.
Supabase observability as a parallel: why the same principle applies to infrastructure metrics
Supabase exposes a Metrics API endpoint compatible with monitoring tools, with Postgres performance and health series, including connection counts, cache hit ratios, WAL volume, and query performance statistics. An external observability stack can scrape these series for alerting and long-term retention beyond what Supabase Studio provides. A scheduled check can therefore use a defined series to deliver a signal without requiring someone to open Studio and look for it.
Supabase’s documentation shows how to schedule agent prompts to run automated health checks. Hourly health checks cover API and Auth server errors and connection pressure, while daily security reviews cover advisor findings and authentication and authorization failures. Hourly performance checks examine sessions, query regressions, and performance advisors. Each schedule has a distinct operational purpose. Morning resource checks cover sizes, connections, request growth, and supported forecasts, with error-rate changes also included in the detailed Capacity monitor prompt.
This parallels business metric delivery. A defined source feeds scheduled interpretation, which produces a signal where the team monitors operations. The historical record is essential in both cases. If a team waits until it has a question to start collecting data, it has no earlier numbers to help it understand the current one. Instrumenting from day one gives later alerts and comparisons a history to draw on.
Building the governed metric layer without a dedicated data team
A governed serving layer can sound like a warehouse project requiring a six-month engineering effort and a dedicated data hire. The small-team version starts with narrower responsibilities. Definitions are written down and version-controlled, even in a README, rather than reconstructed from memory whenever someone edits a script. Each metric also has a clear owner. Responsibility for the definition of MRR is a people question that must be answered before the delivery system is built.
Access control then makes the separation operational. The data layer gives scripts and agents read-only access to prepared results and keeps them from using production as an analytics query target. This keeps scripts and agents from changing source data by accident when they send results. The definition, calculation, and access rule are maintained upstream. A new email format or agent tool can then use the established result without creating another calculation to reconcile.
A Monday morning Slack digest and a Friday afternoon email summary can use pre-calculated metrics reconciled to their sources, with threshold alerts reserved for signals that cannot wait. Freshness timestamps distinguish an updated value from an older snapshot. Where the reporting period and version match, the Slack message, email, billing source, and agent response should agree. Where they differ, the governed record should make the difference understandable rather than leave the founder to investigate the delivery scripts.